Thursday, December 03, 2015

A combinatorial solution to the sum of squares formula

Overview

In my previous two blog posts, I showed that the number of squares of various sizes in an nxn grid is $\sum_{{i}={1}}^{n}i^2 = \frac{n(n + 1)(2n + 1)}{6}$. In this post I'm going to use combinatorial Mathematics to derive a different closed form solution.

All posts in this series


A quick review of combinations

In combinatorics, the combination function $\binom{n}{k}$ is used to counts the number of different ways that k items can be chosen from a set of n unique items, with the order of the k items being irrelevant. $\binom{n}{k}$ is usually read as "n combination k" or "n choose k". It is also known as the binomial coefficient. You can read more about combinations on Wikipedia.

You also need to know that: $$ \begin{align*} n! &= 1 . 2 . 3 ... n & \text{n! is the product of the first n natural numbers} \\ \binom{n}{k} &= \frac{n!}{(n-k)! k!} \\ &= \frac{n (n - 1) ... (n - k + 1)}{1 . 2 . 3 ... k} \end{align*} $$

The approach

We are going to use combinatorial Mathematics to count the number of possible squares in the grid. To do this we will need to define a coordinate system for the grid and a convenient data representation for a valid square in that grid. By a data representation, I mean a set of numeric values that can uniquely identify a particular square in the grid.

We will then use combinations to count all possible ways of generating valid data representations. But we will need to take into account that combinations generate unique numbers. That will require us to consider separate cases based on the number of identical variables in our representation.

A useful data representation


A recap of the problem

The problem is to count the total number of squares of any size in a grid. So if you think of a Chessboard, how many 1x1, 2x2, ..., 8x8 squares are there?

Let's consider whether there is a useful notation for describing any valid square in the grid.


Defining a coordinate system

First let's define a coordinate system for the grid.

We'll say that (x, y) is the coordinate of a space on the checkerboard in column x and row y. And we'll choose (1,1) to be the coordinate of the top-left corner. That way columns go from left to right and rows go from top to bottom - the same direction as reading pages in a book (for most cultures).

[This is just one possible convention... I could have started at the bottom left instead, like a chart, or made the corner square (0, 0) instead of (1,1).]


Comparing different representations for valid squares in the grid

We could use the co-ordinates $(x_1, y_1)$ and $(x_2, y_2)$ of two opposite corners of a square block. But that representation encodes any rectangle in the grid, not just the squares. We'd prefer to choose a data representation which enforces constraints naturally.

So what if we used $(x_1, y_1, s)$ as our data representation, where $(x_1, y_1)$ is the top left corner of the square and $s$ is the size of the sides of the square? This is better, because we have 3 variables representing a valid square instead of 4, and we have expressed the constraint that a square's sides have the same size.

However this representation is still a little cumbersome. To express the constraint that the square fits within the grid, we need to ensure that the bottom right corner is somewhere inside the grid. That requires calculating the x and y coordinates of the bottom-right corner. Our data representation would be more convenient if we could avoid all unnecessary calculations.

So let's encode the bottom-right corner into the data representation instead. This will give us our desired data representation...


The chosen data representation

We will represent a square in the grid by the triple $(x, y, s)$ where (x, y) is the bottom-right corner of the square and s is the size.

Our data representation (x, y, s) is summarized in the following diagram:

With this data representation, our constraints on a valid square are: $$ \begin{align*} 1 \leq x \leq n & \tag{1} \\ 1 \leq y \leq n & \tag{2} \\ 1 \leq s \leq n & \tag{3} \\ s \leq x & \tag{4} \\ s \leq y & \tag{5} \\ \end{align*} $$

There is some redundancy in constraint 3, since the other 4 constraints ensure that $s \leq n$. I've chosen to do it this way so that constraints 1, 2 and 3 all have the same form. They will be satisfied naturally when we use the combination function. Only constraints 4 and 5 will need to be considered explicitly.


Generating all possible data representations


Choosing values of x, y and s from the set {1, 2, ... n}

We can address constraints 1, 2 and 3 by choosing our variables x, y and s from the set {1, 2, 3, ..., n}. That allows us to use the combination function.

Unfortunately there's a catch! Combinations count unique numbers, and some of the variables x, y and s could be the same. So we'll need to consider separate cases depending on how many of the variables have unique values.

Let's start by defining variables for each case. Let $c_i$ be the number of ways of generating representations $(x, y, s)$ when $i$ unique numbers are taken from the set {1, 2, 3, ..., n}. The total number of squares is then $c_1 + c_2 + c_3$.


Counting $c_3$: the number of squares when x, y and s are all different

There are $\binom{n}{3}$ ways of choosing three unique numbers from the set {1, 2, ..., n}. Of these, the smallest must always be assigned to $s$ so that constraints 4 and 5 are addressed. However the largest could be assigned to x or y. This leads to two sub-cases: $$ \begin{align*} \text{ i) } & s < x < y \\ \text{ii) } & s < y < x \end{align*} $$

So we have two different representations generated from each set of three distinct numbers. Thus: $$ c_3 = 2 \binom{n}{3} $$


Counting $c_2$: the number of squares when only two of x, y and s are different

There are $\binom{n}{2}$ ways of choosing two unique numbers from the set {1, 2, ..., n}. But there are three different ways that these two numbers can be assigned to the values (x, y, s): $$ \begin{align*} \text{ i) } & s < x = y \\ \text{ ii) } & s = x < y \\ \text{ iii) } & s = y < x \\ \end{align*} $$

Thus: $$ c_2 = 3 \binom{n}{2} $$


Counting $c_1$: the number of squares when x, y and s are all the same

There are $\binom{n}{1} = n$ ways of choosing a single number from the set {1, 2, ..., n}.

Each such number will define a single solution with: $$ \begin{align*} s = x = y \\ \end{align*} $$ Clearly all the constraints will be satisfied. Thus: $$ c_1 = n $$


Putting it all together

So the total number of squares of various sizes in an n x n grid is: $$ c_1 + c_2 + c_3 = n + 3 \binom{n}{2} + 2 \binom{n}{3} $$


Checking the answer

In the second post of the series we showed that the number of squares is $ \frac{n(n + 1)(2n + 1)}{6} $. Let's check our answer by seeing if the two formulas are equivalent.

$$ \begin{align*} n + 3 \binom{n}{2} + 2 \binom{n}{3} &= n + 3 \frac{n (n - 1)}{2} + 2 \frac{ n(n - 1)(n - 2)}{6} \\ &= \frac{n}{6} [ 6 + 9 (n - 1) + 2(n - 1)(n - 2) ] & \text{ Extract } \frac{n}{6} \text { from all terms } \\ &= \frac{n}{6} [ 6 + 9n - 9 + 2n^2 - 6n + 4 ] \\ &= \frac{n}{6} [ 2n^2 + 3n + 1 ] \\ &= \frac{n}{6} [ (n + 1)(2n + 1) ] \\ &= \frac{n(n + 1)(2n + 1)}{6} \\ \end{align*} $$ So our calculations seem correct, since this is the formula we generated in the previous blog post.

The value of a good data representation

Rob Pike's 5th rule of programming supposedly states that:

Data dominates. If you've chosen the right data structures and organized things well, the algorithms will almost always be self-evident. Data structures, not algorithms, are central to programming.

This echoes Fred Brooks' statement in "The Mythical Man-Month" that: "Representation is the essence of programming".

This blog post is about Mathematics, not programming. But I'd argue that the elegance of this solution also comes from choosing the right data representation.

Conclusion

This is the third post in the series. The first three posts have shown that the number of squares in an nxn grid is: $$ \begin{align*} & \sum_{{i}={1}}^{n}i^2 & & \text{ from blog post 1} \\ = & \frac{n(n + 1)(2n + 1)}{6} & & \text{ from blog post 2} \\ = & n + 3 \binom{n}{2} + 2 \binom{n}{3} & & \text{ from blog post 3} \\ \end{align*} $$


Next time

This post had far less algebra than the previous blog post. But there was still some algebraic manipulation required to arrive at the formula $\frac{n(n + 1)(2n + 1)}{6}$. It's certainly not obvious why the formula has that specific form. My aim in the next two blog posts will be to address this. I want to arrive at that formula via a much more direct route.

Wednesday, December 02, 2015

Guessing a closed form solution for the sum of squares

Overview

In a previous blog post, I showed that the number of squares of various sizes in an nxn grid is $\sum_{{i}={1}}^{n}i^2 $. As n gets large, it's going to take a long time to sum up all those squares. So a closed form solution would be much better.

In this blog post I'm going to demonstrate a very mechanical way of finding that formula. It doesn't require any flashes of genius, and it generalizes to many similar problems. If you were the manager of a team of Mathematicians selling commercial Mathematics projects, this is probably how you'd want them to solve the problem. It's boring, predictable, general and doesn't require (nor provide) any special insight. And you can even solve the algebra programmatically, which will reduce the risk of a calculation error. Kaching!

What? You don't work for a company that sells Mathematics for money? How surprising. Well, stay tuned to this blog series. Because in future blog posts I'm going to present a variety of more inspired solutions. These will give much better insight into why the formula comes out the way it does. But first let's derive the formula...

All posts in this series


The mechanical approach


Step 1: guess the pattern of the formula

The degree of a polynomial is the highest power that the variable is raised to. If the summation is over a polynomial of degree $d$, then make an educated "guess" that the closed form expression is a polynomial of degree $d+1$. This seems plausible, because it holds for the following well known formulae: $$ \begin{align*} \sum_{{i} = {1}}^{n}1 &= n \\ \sum_{{i} = {1}}^{n}i &= \frac{n(n+1)}{2} &= \frac{1}{2} n^2 + \frac{1}{2} n \\ \end{align*} $$

Firstly, let $f(n) = \sum_{{i}={1}}^{n}i^2 $ be the actual sum of squares function.

Note that $f(0) = 0$ since there are no terms to add when $n = 0$ (there are zero squares in a zero by zero grid).

Now let $g(n)$ be our guess for the closed form equivalent of function f: $$ \begin{align*} g(n) &= \sum_{{j}=0}^{d+1}a_j.n^j \\ &= a_{0} + a_{1} n + a_{2} n^{2} + a_{3} n^{3} & \text{since d = 2} & \tag{1} \end{align*} $$

Next we need to calculate values for the $a_j$ values. We will start with $a_0$.


Step 2: Ensure that $g(0) = f(0) = 0$

$ g(0) = a_3 . 0^3 + a_2 . 0^2 + a_1 . 0 + a_0 = a_0 $

Hence set: $a_0 = 0 \tag{2}$


Step 3: Choose a method for determining the other coefficients

At this point it's tempting to set $g(1) = f(1)$, $g(2) = f(2)$ and $g(3) = f(3)$ to calculate the coefficients $a_j$. This is quick and simple and it will generate the correct values of the $a_j$ if $f(n)$ is indeed a polynomial.

But it won't provide any justification that $f(n)$ really is a polynomial of degree $d + 1$ i.e. that $f(n) = g(n)$ for all non-negative integers $n$. To be more rigorous, we are going to calculate the coefficients a different way...

Let $h(i)$ be the expression in the summation i.e. $h(i) = i^2 \tag{3} $

[Note that you can generalize this method using other polynomial functions for $h$.]

We are going to choose values for the $a_j$ coefficients so that: $$ \begin{align*} g(i) - g(i-1) &= h(i) & \forall i \in \mathbb{N} & \tag{4} \\ \end{align*} $$

Providing we can find such values, this will enable us to prove that $$ \begin{align*} g(n) &= f(n) & \forall n \in \mathbb{N} \end{align*} $$ This is because:

$$ \begin{align*} f(n) &= \sum_{{i}={1}}^{n}h(i) \\ &= \sum_{{i}={1}}^{n}[g(i) - g(i-1)] \\ &= [g(n) - g(n-1)] + [g(n-1) - g(n-2)] + ... + [g(2) - g(1)] + [g(1) - g(0)] \\ &= g(n) - g(0) & \text{because all other terms cancel out} \\ &= g(n) & \text{since } g(0) = 0 \text{ by equation 2} \end{align*} $$

There's some tedious and error-prone algebraic manipulation involved in calculating $g(i) - g(i-1)$. Instead of doing it by hand, let's use symbolic mathematics software to do it for us...


Step 4: Determine the other coefficients programmatically

First let's make some technology choices:

  • Use the Python programming language, since it is popular in the Scientific community.
  • I already have Python 2.7.10 installed via the PythonXY scientific Python distribution for Windows.
  • Use the SymPy Python library as our symbolic Mathematics package.
  • Use the iPython notebook as our REPL, as it allows easy sharing of the code.
  • Store the notebook in GitHub, which has built-in support for hosting and displaying iPython notebooks.
  • Extract the code into a separate Python script, and copy this script into a GitHub gist for easy sharing in the blog.

The first step was to develop the SymPy code in an iPython web notebook. You can download or view the notebook on GitHub.

If you download it, you can then open it from the command line by navigating to a suitable folder and running

ipython notebook --ip=localhost

This will open a local web page which you can use to navigate to the notebook and edit it:

After calculating the coefficients and factorizing the polynomial, the notebook spits out the following formula: $$ \frac{n(n + 1)(2n + 1)}{6} $$


Step 5 (optional): Generalize the code to work for other polynomial summations

After getting the code working using the iPython Notebook, I ported it to a Python script. I then modified the script so that, instead of only supporting the case $h(i) = i^2$, it would accept any polynomial expression in the variable $i$ as a command line parameter.

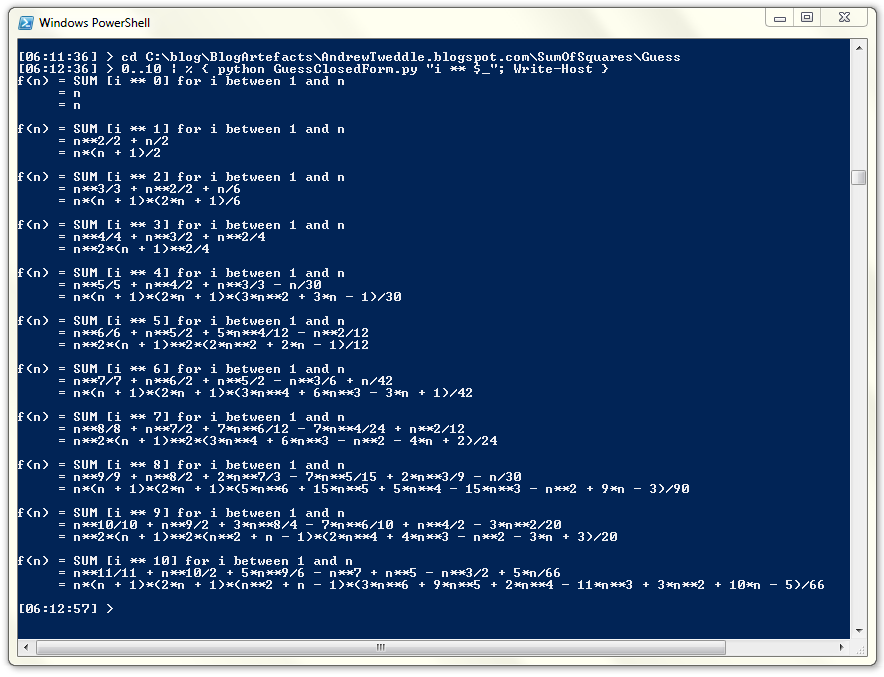
To demonstrate that this method works more generally, I've included a short Powershell snippet to calculate the closed form of the sums of kth powers for k from 0 to 10:

Running this Powershell snippet, produces the following output:

I'm fairly happy with how the Python script turned out in the end. But I found it quite frustrating getting to that point. While SymPy is reasonably well documented at the level of modules and functions, it's harder to work out what the allowed values are for many of the function parameters and what they mean. Although the code is working, there are still quite a few hacks and TODO's left in the code.

As well as using the official SymPy documentation, I also found this SciPy 2011 Tutorial quite useful.

It would have been quicker to do the algebra by hand, although admittedly not for the more general case. Arguably that's also due to my lack of regular practice with SymPy, iPython and Python.


Conclusion

In this blog post I've used SymPy to derive the following result: $$ \sum_{{i}={1}}^{n}i^2 = \frac{n(n + 1)(2n + 1)}{6} $$

In my next few blog posts on this problem, I'm going to demonstrate other derivations of the closed form solution. In particular, I'm looking for derivations which provide greater insight into the problem.

Wednesday, June 10, 2015

Counting squares in a grid using the sum of squares method

Introduction

A while back a colleague asked some of us how we would go about solving a particular Mathematical problem. The problem was to count the total number of squares in a Chess board. This included all squares of size 1x1, 2x2, up to 8x8.

I found a number of different ways of solving the problem which I'm going to present in the next few blog posts.

As has been the theme with my previous blog posts on Mathematical puzzles, my goal is to progress from solutions which are algebraic to solutions which provide insight.

This blog post is about the first way of solving the problem, which I've dubbed the sum of squares method.

Note that I'll be solving the problem for any n x n grid (or lattice), not just for the 8 x 8 chessboard.

All posts in this series


Step 1: How many k x k squares fit into an n x n grid?

Supposing we have an n x n grid. In how many different ways can we fit a square of size k x k into the grid (and of course its edges must align with edges inside or along the edge of the grid)?

Consider the k x k pink square shown in the diagram below...

I've shown the top-left cell of the pink square in a darker pink. We can't move the dark pink square any further right or down. But we could move it up or to the left. As we move the square around, the dark pink cell can end up anywhere within the yellow area.

So the number of possible positions for the pink k x k square is precisely the number of positions for the dark pink cell, which is the size of the yellow area.

Now the yellow area has sides of length: $n - (k - 1) = n - k + 1$. So there are $(n - k + 1)^2$ possible k x k squares that can fit into the n x n grid.


Step 2: Add up the number of squares for each value of k

The smallest value of k is 1 and there will be $n^2$ one-by-one squares fitting in the grid. The largest value of k is n and there will be only one n x n square.

If we add up the number of k x k squares for each value of k we get a formula of:

$$ \sum_{{k}={1}}^{n}(n - k + 1)^2 $$
That's quite a neat formula. But we can make it even neater by adding a new variable $i = n - k + 1$ and summing over all possible values of $i$ instead. The following table will make this clearer:

$k$ $i = n - k + 1$ Number of squares of size k x k
$ = (n - k + 1)^2 = i^2$
$1$ $n$ $n^2$
$2$ $n - 1$ $(n-1)^2$
... ... ...
$n - 1$ $2$ $2^2$
$n$ $1$ $1^2$


Now instead of summing over the values of k (from top to bottom), we can instead sum over the values of i (i.e. starting from the bottom row to the top row). And our formula becomes: $$ \sum_{{i}={1}}^{n}i^2 $$

Step 3: Derive a closed form solution

The formula above is very succinct and beautiful. But it has a drawback... as $n$ gets large, it's going to a take a long time to do all those summations. To address this, what we really want to find is a closed form solution without any summation symbols.

In future posts I'm going to show you a few different ways of getting a closed formula.


Next steps...

In the next blog post in this series, I'm going to derive the closed form solution through algebraic manipulation of the summation formula.

In later posts I will derive the number of squares in the grid in other ways. These will lead directly to the closed form solution. I'm hoping they will also give more insight into why the formula comes out the way it does.

Sunday, March 02, 2014

Andrew Loves Math(s)

Introduction

The other day I was discussing Mathematical puzzles with my colleagues and one of them mentioned the "Johnny Hates Math" problem. The problem statement can be found on the SPOJ web site.

Essentially the problem is to insert plus signs at appropriate places in a string of digits such that the resulting sum equals a target value. The plus signs will divide the digits into a set of numbers. None of these numbers should be more than 5 digits long and none should start with a zero, except possibly the number zero itself.

The instructions on the SPOJ web site are to print out the solution with the least number of plus signs. But I think it's more interesting to know the total number of solutions. So I'm just going to provide code to solve that problem, not satisfy the SPOJ specification.

I'm going to solve the problem in a number of different ways and using different programming language features (mainly using Scala). The purpose is to get a feel for which solution methods produce the most concise code and which produce the fastest code. It will also be an opportunity to experiment with Scala and develop more of a feel for the language.

A PowerShell solution

My first attempt was in PowerShell and took 46 minutes to code. A lot of that time was spent fixing PowerShell syntax errors.

Interestingly, I automatically turned to recursion to solve the problem. I guess that's the effect of experimenting with functional programming in the last little while!

My approach was to:
  • Branch on the number of digits in the next number (line 6 in the code snippet below)
  • Prune each branch based on having enough digits left (line 8), not starting with a zero (line 11), not exceeding the target value (line 16) and not running out of digits before reaching the target value (line 25)
  • Recursively call the function with the remaining digits and remaining target value (line 28)
  • End the recursion when there are no digits remaining and the target value has been reached exactly (line 21)

A quick comment on line 28: @(...) wraps its contents in an array unless the contents are already an array. This solves a problem in PowerShell where, if a function or script emits multiple values, these values are automatically wrapped in an array - but if there is only a single value, then it is returned as is.

This inconsistency can lead to some very tricky bugs. So it's important to coerce the return value to an array.

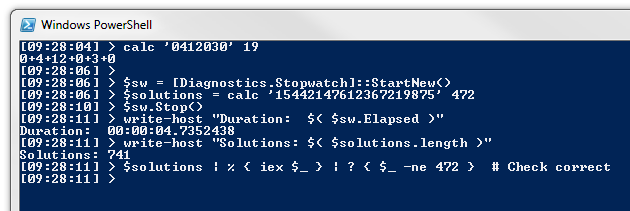
My laptop has an i5-2430M CPU. The PowerShell script solved the problem in under 5 seconds for the problem of inserting plus signs into the left hand side of: 15442147612367219875=472


The break statements provided a very convenient way of excluding infeasible branches. This didn't feel as clean in my first Scala attempt, since Scala treats if statements as expressions (similar to the ?: ternary conditional operator in languages like C# and Java).


A few Scala solutions


A Scala base class for the solver algorithm

I refactored the algorithm-independent features into a base class. The code for this is shown below:


I made the somewhat strange decision of defining the abstract solve method to take the same parameters as the class constructor. This was purely to give the derived classes the option of recursively calling the solve method. But it's not a great API design choice. It feels like it is trying to be both a static method (although Scala doesn't have such a concept as it would violate pure OO) and an abstract method.

I'm uncomfortable with this API, which usually means something's wrong. But I'm going to leave it for now, because my focus is on solving the problem, not designing an API.

In line 19, the companion object uses the "SolverUsingFlatMap" derived class as its default solver. I'll provide that sub-class next...

Scala solution 1: SolverUsingFlatMap

The code for my first Scala solution is shown below:


This solver works in a very similar fashion to the PowerShell algorithm. However, instead of returning arrays of strings, it represents a single solution as a List[Int] (i.e. a Scala linked list of integers). A list of solutions is then represented as a List[List[Int]].

I returned an empty list of solutions to indicate that a branch was infeasible. But the break statements in PowerShell felt a bit more intuitive to me.

Scala solution 2: SolverUsingFor

I wanted to get away from returning empty lists as a way of indicating a failed branch. My first thought was to use an Option[List[List[Int]]] type to represent a pruned branch using an option of None. But this felt like overkill.

Instead my second attempt used a for statement to get away from the need to return empty lists. This code turned out to be very concise and pleasing:


Scala solution 3: SolverUsingFoldLeft

I then started wondering whether it was possible to use a foldLeft operation to calculate a solution.

There were a few conceptual issues with making this work. Firstly, a foldLeft is taking a fixed list of items and an initial accumulator, and updating the accumulator for each successive item. In this case, each item was an individual digit.

Secondly, all the previous solutions branched in up to 5 directions at each step. To get branching to work with foldLeft, I needed to store all the branches in the accumulator. To do this, I created a PartialSolution class to keep track of the numbers generated so far, as well as the current number which was being built up. At each step, I would then split each PartialSolution into at most 2 new PartialSolutions, by either terminating the current number or adding another digit to it.

The code is shown below:


This code is considerably more verbose. I also didn't expect it to perform very well. Firstly, it is effectively doing a breadth-first search. Secondly I would expect it to be more memory-intensive and memory access is often much slower than computation. This is partially mitigated by storing the numbers in reverse order (so that large parts of the previous level's data structures are reused, since prepending a number to a list does not create a new list). Also, the foldLeft is tail recursive.

I also expected the foldLeft solution to degrade very quickly for large target totals, as the number of partial solutions is potentially doubling in size at every step. So with a large target value, the pruning effect of comparing the running total to the target is lost.

It turns out that this solver performed a lot better than I expected. And although it did degrade more with larger totals, the effect was not as pronounced as I had been expecting.

Scala worksheet to compare performance of the solvers

I used a Scala worksheet to test the code and compare performance of the various algorithms. The worksheet code and results are shown below:

[UPDATE: This way of measuring performance is not ideal, as explained in this blog post by Aleksey Shipilёv. Rather use a micro-benchmarking framework, such as JMH (possibly with sbt-jmh) or ScalaMeter.]

I tested the 3 solvers twice - first using a low target value, and then again using a high target value (to get an idea of the scalability of the algorithms).

There are some interesting things to note here.

Firstly, the flatMap method was fastest in all cases.

Despite being so short, the method using for comprehensions was much slower. In fact, for the smaller target value, I was quite surprised to see that the breadth-first foldLeft solver was sometimes faster!

With a much larger value, the foldLeft solver showed its poor scalability. However it wasn't that much worse than the method using the for comprehension.

All the Scala solvers were much faster than the PowerShell algorithm. This isn't too surprising, since PowerShell is an interpreted scripting language.


Impressions of Scala

Last year I completed the two Scala courses given on Coursera. This was my first foray into Scala since completing those courses. So what are my impressions of the language?

Programming in the small

Firstly, I've really enjoyed solving this problem with Scala. As with F#, I love being able to have concise, readable code - not unlike a dynamically typed language - and yet still gain the benefits of type safety and good performance.

I can see how functional programming in general provides a great solution for "programming in the small".

Scripting

Scripting is another aspect of programming in the small. So at some point I'd like to experiment with using the Scala REPL for writing scripts.

There is definitely promise in this area. I've had a lot of experience using PowerShell for scripting at work and at home. But I've had colleagues demonstrate that they can generally match the features of PowerShell using the F# REPL. It's obvious that functional programming languages can mount a credible challenge in this space - at least from a language perspective. The major advantage PowerShell continues to have in a work setting is its ubiquity on Windows servers.

I also recently finished working on a "record linkage" challenge in my spare time using Python and Pandas for the data munging. If and when time permits, I would like to re-develop the project in Scala to see which code base is easier to work with.

Programming in the large

Something I really like about Scala is that it is clearly designed for "programming in the large" as well. It's not just about functional programming. The baby has not been thrown out with the bathwater: object orientation is treated as an equal citizen in the language.

Actually I'd argue that Scala's true potential in the enterprise has very little to do with being a functional programming language. There are many Scala features which allow very concise, readable Object-Oriented code to be written. This succinctness is part of the style of functional programming. However the overtly functional features in Scala are often too easily abused and could be a distraction from the very real value that Scala offers.

I've seen a number of recent indicators that Scala may be ready to break into the enterprise development space:

On the other hand...

Scala has momentum. But that doesn't mean it will achieve breakthrough. Numerous great languages have fallen by the wayside, and there's no guarantee that Scala won't join their ranks. It's a big leap from a language being ready for the enterprise, to the enterprise being ready for a language!

On the negative side, Scala has a lot of very advanced language features which can easily trip up newcomers. This complexity is a substantial barrier to enterprise adoption.

This explains why Thoughtworks qualifies its recommendation of Scala as being just "the good parts".

Rod Johnson also addresses this issue in the ScalaDays keynote mentioned earlier, emphasizing the need to favour readability over poetry.

Martin Odersky, the designer of the Scala language, is well aware of the challenge. In 2011 he provided a list of language features with recommendations for which features were suitable for different levels of application developers and which for library designers.

Library design

This raises another area where Scala appears to be very elegant... library design.

The hammerprinciple.com site has Scala at number 3 for "I rarely have difficulty abstracting patterns I find in my code" and "this language is expressive". It comes in at number 2 for "I find code written in this language is very elegant". These suggest that Scala could be a great language for designing libraries for Scala and the JVM.

Of course you have to take this with a pinch of salt, since early adopters are likely to bias the HammerPrinciple survey outcomes. However there seems to be enough promise here to justify further experimentation.

On that note, there were some things in my JHM code that I really didn't like. I want to refactor the solve() method. And even though it's only in a worksheet, I'd also like to get rid of the implicit parameter to the time() function. It's one of those features which can easily make a code base more opaque. And even though the way I've used it is fairly transparent, just the act of using it legitimizes its use by less experienced programmers (who either haven't developed the intuition to know when not to use the feature, or don't yet have the ability to hold their peers to account by being able to explain the reasoning behind that intuition).

In a later post I'd like to refactor the code for reusability, and in so doing understand more of Scala's library design features.


Conclusion

This has been an interesting algorithmic challenge and I have really enjoyed solving it with Scala.

I've seen enough promise with Scala to justify using it as my preferred hobby language (along with Python for experimenting with Data Analytics and data munging).

It's been a lot of fun programming with Scala. And that's pretty important, because there's no guarantee that it will ever become a marketable skill.

Thursday, February 27, 2014

RIP Amber

Today we took our beautiful bull mastiff to be put down. Heart-breaking, but necessary... she was over 10 years old and had been diagnosed with kidney failure. She was skipping meals and her weight had dropped to just 34 kilograms (from 51 kg a few years before).

She had a wonderful sniff around the vet's waiting room, and it was lovely to see some of her old joy and bounciness back. But it also brought back memories of her younger self. It made it all the sadder to say good-bye and stroke her head as she fell asleep for the last time...

RIP, Amber!

Sunday, February 23, 2014

Birthday Board Games Bash

Thank you!

Firstly, a big thank you to my wonderful wife for arranging a board games party on Saturday for my birthday.

Around 40 friends attended, with the numbers being fairly evenly split between adults and children. We started at 10:00 am, and things went very smoothly, despite a power outage to replace some stolen electrical cable in the area.

There were 3 separate groups of friends present. I was a little apprehensive as it's always difficult to mix different social groups together. But it went really well.


Ricochet Robots

We started out playing Ricochet Robots as it can handle an arbitrary number of people and it's easy to join or leave at any time. It's a very clever competitive puzzle and it can be a real brain-burner. It's not everyone's cup of tea, but I love it!

There are online versions at http://www.ricochetrobot.com and http://www.ricochetrobots.com.


The Resistance: Avalon

Two of my friends had brought along copies of Avalon (the Resistance) so we then split into two groups - one for novices and the other for the experts. I played in the expert group, but felt a bit out of my depth at first.

There are a group of us who play games once a week after work. The rest of the guys have been playing Avalon a lot over the past few months and even have their own terminology now. But over that time I was temporarily seconded to another project to produce an architecture document for a client. So I have a lot of catching up to do.


A present!

Although everyone had been instructed not to bring presents, my colleagues clubbed together to buy me a present anyway. They had colluded with my wife, who had sneakily found out which games were on my most desired list. So I received a copy of Libertalia.

This game has been a big hit in our weekly after-work games sessions. It's a lot of fun to play. So I was delighted!


Ultimate Werewolf

After one of the Avalon owners left the party, we ended up with around 15 people still wanting to play. Although the Resistance improves on Werewolf in just about every way, it only caters for up to 10 players. Werewolf can handle much more than that.

So we switched over to a few games of Ultimate Werewolf instead. Great fun as always!


The birthday buffoon!

As numbers dwindled, we switched back to Avalon again. We ended with an absolutely excellent game, where the minions of Mordred won all 3 quests and also knew who Merlin was.

I ended up being a perfect patsy for two of the minions of Mordred, who inveigled their way into the trusted group. It was so impressive to see how cleverly they pulled the wool over our eyes, that I felt honoured to have been part of the game - even if I was one of the ones who had been so comprehensively fooled by them.

Usually our monthly board games events last until late into a Saturday night, but this time everyone was gone before supper.


And thanks again!

All in all, it was a really fun way to spend a birthday. Thanks to everyone who attended, and made this an ideal birthday party for me!

Saturday, February 08, 2014

Researching the Josephus problem


All posts in this series:

  • One Potato: A description of the problem
  • Two potato: The basic equations
  • Three potato: An algebraic formula for the last person left
  • Four: A neat calculation method using binary numbers
  • Five potato: F# functions to check the various formulae
  • Six potato: Using a calculation graph to see the pattern
  • Seven potato: Generalizing to other intervals
  • More: An efficient algorithm for arbitrary intervals
  • Online research: In which I discover that it is called the Josephus problem

Introduction

This is the ninth post in a series about an interesting Mathematical problem known as the Josephus problem.

Imagine a number of people sitting in a circle. Every second person is asked to leave the circle. This continues until only one person is left. If you label the people 1 to n, what is the label of this last person?

In the first 6 posts in the series:
  • I derived a formula for the label of the last person left,
  • I provided various proofs of the formula, and
  • I wrote code in the F# programming language to calculate the answer in various ways.

In the seventh and eighth posts I created an efficient algorithm for calculating the answer when the number of people skipped is not two but some arbitrary interval k. But I wasn't able to find a closed formula. And I felt I had gone as far as I could on my own. It was time to see how other people had solved the problem.

This post is about what I discovered.


The problem has a name

The first thing I discovered is that the problem has a name. It is known as the Josephus problem and it is widely used in Mathematical and Programming challenges. So I will be updating the previous posts to reflect the accepted name.

You can read more about the history of the Josephus problem on Wikipedia or Wolfram Mathworld.


In search of an elegant solution


My own attempt

When there are n people in the circle labelled 1 to n, the formula for the last person left in the circle is: $$ f(n) = 2n + 1 - 2^{{\lfloor log_2 n \rfloor} + 1} \tag{1} $$
In the third post in the series I used algebra to prove this result. But although algebra is a very powerful tool for proving the formula, it doesn't give any insight into why the formula is true.

One of the challenges I set myself was to provide that insight. The closest I came was in the sixth post in the series, where I used a calculation graph to show the pattern of values for $f(n)$.

Chamberlain's solution is much more elegant...

Chamberlain's solution

Chamberlain's Solution can be found on page 403 of Problem Solving and Recreational Mathematics 2012 by Paul Yiu of Florida Atlantic University.

His solution is based on a few key insights. I've paraphrased these as follows:
  1. When the number of people in the circle is a power of two, the last person left is the first person skipped. This is because:
    1. All the even numbered people are skipped each time around the circle
    2. Exactly half the people are eliminated, so the remaining size of the circle is again a power of two
    3. Person one will still be the first person skipped on the next traversal of the circle
    4. So the process repeats itself with the circle halving each time, until person one is the only person left

  2. Suppose the size of the circle is $2^m + r$ (with $0 \le r < 2^m$). Carry out the first $r$ removals. Then:
    1. The first $r$ people removed are persons $2, 4, 6, ..., 2r$
    2. The next person to be skipped will be person $2r + 1$
    3. This leaves a new, smaller circle with $2^m$ people
    4. So we can apply the rule from point 1 above (for a circle of size $2^m$)
    5. So person $2r + 1$ will be the last person left in the circle

Making it rigorous

There are a few points above which may not be obvious. Let's try to make them more rigorous:

In point 2.a., the assumption is made that the labels of the first $r$ people removed would not "clock over" (i.e. one revolution of the circle hasn't been completed). Is this assumption reasonable?

$$ \begin{align*} \text {By definition: } 0 & \le r < 2^m \tag{2} \\ \text {and: } n & = 2^m + r \tag{3} \\ \\ \therefore 2r & < 2^m + r &\text{ by adding r to both sides of the inequality on the right of (2)}\\ \text{i.e. } 2r & < n \tag{4} \\ \\ \text{Also: } 2r + 1 & \le n \tag{5} \end{align*} $$
Equation 4 shows that this is a reasonable assumption.

In point 2.b. we also assumed that the next person to be skipped will be person $2r + 1$. Equation 5 proves that this label doesn't "clock over" either.

So this proves that $f(2^m + r) = 2r + 1 \text{ where } 0 \le r < 2^m$.

And this can be re-expressed in terms of logarithm and floor functions by noting that:
$$ \begin{align*} 0 & \le r < 2^m & \text{ from equation 2} \\ \therefore 2^m & \le 2^m + r < 2^m + 2^m \\ \therefore 2^m & \le n < 2^{m+1} & \text{ from equation 3} \\ \therefore m & \le \log_2{n} < m+1 & \text{ since logarithms are monotonic (order-preserving) } \\ \therefore m & = {\lfloor log_2 n \rfloor} \tag{6} \\ \\ \text{So:} \\ f(n) & = 2r + 1 \\ & = 2( n - 2^m ) + 1 & \text{ from equation 3}\\ & = 2n + 1 - 2^{m+1} \\ & = 2n + 1 - 2^{{\lfloor log_2 n \rfloor} + 1} & \text{ from equation 6} \end{align*} $$
And this is the formula given in equation 1 earlier.

A beautiful visualization of Chamberlain's solution

You can find a beautiful visual explanation of this solution on the Exploring Binary web site.

Another very succinct solution

I was also very impressed by this solution. But although it was very succinct, I didn't feel that it provided the same "aha" moment of Chamberlain's solution.


Generalizing the Josephus problem to arbitrary intervals

I found two algorithms for generalizing the Josephus problem to arbitrary intervals.

Jakobczyk's algorithm

One of these was in a paper entitled On the Generalized Josephus Problem by F Jakobczyk. Although interesting in its own right, I'm rather going to concentrate on the other algorithm I found, as it was far more elegant...

The Ahrens-Schubert algorithm

I found the first page of an article by I. M. Davids published by the Applied Probability Trust. This page gives a very elegant algorithm for the Josephus problem generalized to arbitrary intervals. But since only the first page (with the abstract) is provided, I don't have a proof for the algorithm.

The Ahrens-Schubert solution uses a number series known as an Ahrens array. These are also referred to in the paper as "rounded up" arrays. They are similar to geometric sequences, except that the answer is rounded up after every step. So each term is the previous term multiplied by a factor $f$ and then rounded up to the nearest integer.

Suppose $a_0$ is the initial integer term. Then: $$ \begin{align*} a_1 & = \lceil{a_0 . f}\rceil & \\ a_2 & = \lceil{a_1 . f}\rceil & = \lceil{\lceil{a_0 . f} \rceil . f} \rceil \\ & ... \\ a_m & = \lceil{a_{m-1} . f}\rceil &= \overbrace{\lceil{ \text{ ... } \lceil{\lceil{a_0 . f} \rceil . f} \rceil} \text{ ... } .f \rceil}^\text{m times} \\ \end{align*} $$

The Ahrens-Schubert solution works by finding the largest number (say $a_{m}$) in this series which is less than $kn+1$, where $k$ is the interval to skip and $n$ is the number of people in the circle. The answer is then $ kn + 1 - a_m$.

But what are the values for $a_0$ and $f$ in the rounded up series?

Well, one neat thing about the Ahrens-Schubert solution, is that by choosing different values for $a_0$ it can determine not just the last person left in the circle, but any arbitrary $e^\text{th}$ person removed from the circle. Here are the parameters: $$ \begin{align*} f & = \frac{k}{k-1} \\ a_0 & = k(n - e) + 1 \\ \therefore a_0 & = 1 & \text{when determining the last person left in the circle (set } e = n \text{)}\\ \end{align*} $$

The Ahrens-Schubert solution for $k = 2$


Something else I like about the Ahrens-Schubert solution is how cleanly the closed formula for $k = 2$ emerges from the algorithm. When $k = 2$: $$ \begin{align*} f & = \frac{2}{2 - 1} = 2 \\ a_0 & = k(n - e) + 1 = 2(n-e) + 1 \\ \text{ or: } a_0 & = 1 & \text{for the last person left in the circle}\\ \therefore a_m & = \overbrace{\lceil{ \text{ ... } \lceil{\lceil{a_0 . f} \rceil . f} \rceil} \text{ ... } .f \rceil}^\text{m times} \\ & = \overbrace{\lceil{ \text{ ... } \lceil{\lceil{1 . 2} \rceil . 2} \rceil} \text{ ... } .2 \rceil}^\text{m times} \\ & = 2^m &\text{since the ceiling falls away as all terms are integers} \end{align*} $$ So the answer is $2n + 1 - 2^m$ where $2^m$ is the largest value of $a_i = 2^i$ less than $2n + 1$. And this reduces to equation 1!

My implementation of the Ahrens-Schubert algorithm

Below is my implementation of the algorithm in F#:
let rec getLargestTermInRoundedUpGeometricSeriesBelow 
        (startValue:int) (factor:double) boundary =
    if startValue >= boundary then
        raise (
            System.ArgumentException(
                "The starting element in the series is not below the bound!"))
    else
        let nextValue = int (System.Math.Ceiling( (double startValue) * factor ))
        if nextValue >= boundary then
            startValue
        else
            getLargestTermInRoundedUpGeometricSeriesBelow nextValue factor boundary

let calcEliminationNumberInCircleWithIntervalByRoundedUpSeries 
        eliminationIndex interval sizeOfCircle =
    let dInterval = double interval
    let factor = dInterval / (dInterval - 1.0)
    let bound = interval * sizeOfCircle + 1
    let initialValue = interval * (sizeOfCircle - eliminationIndex) + 1
    bound - getLargestTermInRoundedUpGeometricSeriesBelow initialValue factor bound

let calcLastLeftInCircleWithIntervalByRoundedUpSeries interval sizeOfCircle =
    calcEliminationNumberInCircleWithIntervalByRoundedUpSeries sizeOfCircle interval sizeOfCircle


Performance of the Ahrens-Schubert algorithm


Below are timings for the algorithm:


These are the same inputs as I used in my own algorithm from post 8 of the series, shown below:


Comparing the timings, you can see that the Ahrens-Schubert algorithm is noticeably faster. It took 0.9 seconds to my algorithm's 1.2 seconds when k = 2, and 2.4 seconds versus 2.6 seconds when k = 100.


Other references


Code to solve the Josephus problem

Implementations in a variety of languages can be found on the Rosetta Code web site.

More research on the Josephus problem

I found an extensive list of references to the Josephus problem on the puzzlemuseum.com web site. Professor David Singmaster has provided a list of articles on recreational Mathematics. Page 4 of source document 3 lists a large number of articles on the Josephus problem.


Conclusion

In this series of articles, I have tackled and successfully solved the Josephus problem. This includes finding an efficient algorithm when the problem is generalized so that an arbitrary number of people is skipped.

I have discovered that this is a well-known problem with an extensive history and a number of explanations and algorithms, including two that were extremely elegant. This makes it an ideal problem to tackle yourself, as there are extensive online resources to compare your approach against.

Using F# to implement various algorithms has been particularly rewarding. This has piqued my interested in functional programming. As a result, I have started dabbling in Haskell. I also recently completed Martin Odersky's Functional Programming Principles in Scala course on Coursera and the follow-up course on the Principles of Reactive Programming. These are thoroughly enjoyable courses, which I recommend highly.

But I'm glad to be finally wrapping up this series on the Josephus problem. It's definitely time to move onto something new!


Sunday, September 22, 2013

The 2013 Entelect AI Challenge Play-offs

Introduction

Last Saturday evening (the 14th of September), I attended the play-offs of the 2013 Entelect Artificial Intelligence Programming Challenge.

Last year the theme was based on the Tron light-cycles game, but on a sphere instead of a grid. This year the theme was inspired by the 1980's tank warfare game, Battle City.

Here's a whirlwind summary of the game rules...

There are 8 fixed boards ranging in size from about 61x61 to 81x81. Each player has 2 tanks. A play wins by either shooting or driving over the enemy base. Bullets move at twice the speed of tanks, and tanks can shoot each other and shoot through walls. Tanks occupy a 5x5 area. Bases and bullets occupy a single cell. When a wall is shot, the two walls on either side are also destroyed (thus allowing a tank to shoot a path through the walls). If tanks try to move into a wall or another tank, the tank will turn but not move. A tank can only have one bullet in play at a time. So the tank is effectively disarmed until its bullet hits a wall, another tank, a base or the edge of the board. Both players move simultaneously and there are 3 seconds between turns. The players communicate with the game engine via SOAP web service calls.


Last year there were over 100 competitors, but this year the challenge was definitely a few notches up in complexity. In the end there were only 22 contestants. So I was expecting the play-offs to be much quieter than last year. But fortunately it wasn't like that at all.

As with last year's competition the camaraderie was superb. There was a lot of lively chatter. And it was great to put faces to some of the people I had been interacting with on the unofficial google groups forum for the competition.


My path to the play-offs

My first bot

Although I worked hard on my bot, I had also been working crazy hours at work and I was still quite tired. But I was given a couple of days off work to compensate for the long hours I had been working. So I don't think the hours at work affected my productivity too much (I ended up writing over 15 000 lines of code in the 7 weeks of the competition). But I think I made more careless mistakes than I usually would.

Between my own bugs and quite a few bugs and race conditions in the official test harness, I lost most of the final week of the competition to bug fixing. I found myself with a number of really nice algorithms, but with no bot to make use of them!

The result is that I very nearly didn't submit a bot at all. My initial entry used a very basic heuristic of having one tank take the shortest path to attack the enemy base and the other tank attack the closest enemy tank. It had very basic bullet avoidance code which I added at the death (so to speak), and which hadn't been adequately tested.

At that stage I had given up on doing well. My main reason for entering was to attend the play-offs, meet up with some of the other contestants and enjoy the superb spirit of the event. I had very low expectations for my bot and I named it "Vrot Bot".


Vrot Bot

"Vrot" is the Afrikaans word for rotten. Like many Afrikaans words it has become a standard part of English slang in South Africa.

It is pronounced like the English word "fraught", but with a short vowel sound and a rolled "r". But if you're an English-speaking South African, you will mis-pronounce it slightly so that "vrot" rhymes with "bot". So it will sound like "frot bot".


The entry date gets extended

Due to the small number of competitors and some technical issues with the test harness, the competition ended up being extended twice.

This gave me an extra week to put a much more sophisticated bot together. However it was only in the last 24 hours of the competition that my new bot ended up beating the original vrot bot convincingly. And a lot of the new code had not gone through nearly enough testing, so it was bound to be buggy.

On that basis I decided to keep the name Vrot Bot.


Testing, testing, testing...

Last year I came fourth in the competition. My secret sauce was building a WPF user interface that allowed me to play against my bot, save and load games, rewind games to arbitrary points in their history, visualize a variety of parameters at each cell of the board and drill down into the search tree of moves (I used the NegaMax algorithm to choose moves). I ended up with a very robust, well-tested bot.


Although I had planned to do something similar this year, the competition had a much shorter duration than last year and I never quite got there. At one point I had a choice between writing my own test harness and using the official test harness provided by the organisers.

I chose to use the official test harness, because I was concerned about the risk of integrating a C# WCF web service client with the SOAP web service exposed by the Java test harness. So I wanted to test that integration as thoroughly as possible, and my own test harness wouldn't have provided that capability.

I ended up using a variety of simpler methods for testing my bot's logic. However this made the test cycle much slower, and I paid the price in having a much buggier bot. There were many parts of my code which were very poorly tested because I simply didn't have a quick and easy way of forcing the game into the scenario I wanted to test.

If there was only one thing I could change about my approach to this year's competition, it would be to write my own test harness (as well as using the official test harness for testing integrations). That would have given me the ability to load a previously played game at any point in its history, instead of having to wait minutes for the harness to reach the turn where I knew the bug to be.


Performance tuning...

Last year my bot's main weakness was its slow performance. The first and third-placed players both used C++ for their bots, so having good performance gave a distinct competitive advantage. So this year I put a lot more effort into tweaking the performance of my bot.

There's a very true saying that premature optimization is the root of all evil. I was well aware of this. However I also felt that to get really good performance the data structures would need to be designed with performance in mind. And that's something that's not easy to change later if you get it wrong.

With hindsight I shouldn't have spent as much time worrying about performance. The search space for this year's challenge was massive. That meant that a brute force approach was far less valuable than last year. My time would have been better spent improving my testing capability.


The play-offs

The 22 contestants were grouped into 4 round robin pools with 5 to 6 players per pool.

Many of the matches were decided on silly mistakes, so I think many of the other contestants had also been struggling with the same issues: the shorter competition timeframe, a much more complex problem space and difficulties with adequately testing their bots.

My bot performed much better than I was expecting. I topped my pool quite easily, winning 4 of my 5 pool matches.

Strangely enough, my bot seemed to be a lot more decisive than I was expecting. But I didn't think too much of it at the time.

My one loss was on a smaller, fairly open board. Bullet-dodging was something I had tested quite thoroughly. Yet my tanks ran straight into the enemy tanks' bullets instead of dodging them. That was also quite surprising.

My bot's algorithm is based on running through a number of scenarios and, for each applicable scenario, calculating a value for each of the 6 possible tank actions for each tank. At the time I suspected that a number of scenarios had combined to create a cumulative value for moving forward that was greater than the value of either dodging or shooting approaching bullets.

It was only a few days later that I discovered the real reason for the lack of bullet-dodging behaviour... but I'll get to that later.


The elimination round

I was expecting the top 2 players in each pool to go through to the finals at the rAge computer gaming expo on 5 October. However there was a twist in proceedings...

The players were seeded based on how many games they had won in the pool stage. The top 16 seeds went into an elimination round. The elimination round worked as follows: seed 1 played seed 16, seed 2 played seed 15, and so on. The winners of those 8 matches would go through to the finals at rAge.

Although I was one of the top 5 seeds, I had a sinking feeling at this point as a single loss could knock one out the tournament. Imagine my feeling when I saw the board for my knock-out game... It was the same board as my one loss in the pool rounds! And sadly the result was the same... my tanks raced towards the enemy tanks, ate a bullet each and I was knocked out the competition!


I was disappointed and a little irritated that everything had hinged on a single game. At least last year the format was a double elimination, so a single bad game couldn't knock a good bot out of the competition.

On the other hand, my expectations had been low to begin with. So the end result wasn't different from what I had been expecting. And I had the added satisfaction of knowing that my bot had generally been much stronger than expected. So all I could do was be philosophical about the loss...


The debacle of the official test harness

Bots that froze

Something surprising and quite sad happened to some contestants. On start-up their bots froze and did nothing for the rest of the game.

Last year's winner, Jaco Cronje, had this problem on a number of boards. But he won easily when his bot played. Fortunately he won enough games to be one of the lower seeds of the top 16, and during the knockout round he got the board that his bot did not freeze on. He won that game easily and made it through to the finals.

Another competitor, Bernhard Häussermann, had a similar issue which prevented his tank from moving in any of his games. This is very sad when you consider how much effort people put into their entries for the competition.

But was it really his own error that led to the frozen tanks?


The mysterious case of the frozen tanks

In the week after the play-offs Jaco and Bernhard went on a mission to identify the reason for their tanks freezing.

During the final weekend before submission, Jaco had set his bot running through the night to check for weird issues. It had run fine. The competition organisers had said they would use the same test harness to run the competition as they had provided for the players to test against. So how was it possible for Jaco to get a different result during the play-offs?

The details of their digging are on this page of the google group for the competition. Here's the short version...

A number of players had noticed that the id's of the 4 tanks were always 0, 1, 2 and 3. One player would get tanks 0 and 3. The other player would get tank id's 1 and 2. Since tank movement was resolved in the order of tank id's, this ordering made it a little fairer to choose who got precedence when two tanks tried to move into the same space on the same turn.

But in the play-offs the test harness started assigning very large tank id's. This caused out of range exceptions for some of the bots when they tried to save the tank information into a much smaller array.

Perhaps the test harness was modified to run multiple games without requiring a restart, instead of the correct approach of building a "tournament runner application" which would re-start the unmodified test harness between games.


So why didn't my tanks dodge bullets?

On Wednesday I had a hunch about why my bullets didn't dodge bullets. And why they seemed to behave differently to what I'd been expecting.

So on Wednesday evening, after getting home from a Data Science meetup group, I put my hunch to the test.

I simulated a tank id outside the range of 0 to 3. As expected, this caused my bot to also throw an out-of-range exception in the part of my code which configures tank movement sequences.

The reason my bot didn't freeze is that I had put in a fail-safe mechanism to catch any errors made by my bot.

If an error occurred, I would see if my bot had made a move yet. If it hadn't, I would run a very simple algorithm so that it would at least make a move rather than just freezing. My closest tank would attack the enemy base, and my other tank would attack the closest enemy tank. There was no bullet dodging logic, as I didn't want to risk running any extra code that could have been the cause of the original error.

So this explains why my bot had failed to dodge bullets. And also why it had acted so single-mindedly.

I had worked so hard on my scenario-driven bot in the final (extended) week of the competition. And it probably didn't even get used due to this bug. How sad. Since I still won my pool with this very basic bot, imagine what I could have done with my much more sophisticated bot!

[Bernhard was in the same pool as me. So without the tank ID bug I might not have won the pool. But at least my best bot would have been on display.]


To be or not to be bitter

So at this point I have two choices...

Jaco and Bernhard have decompiled the jar file for the official test harness, and there should be no way that the test harness can assign a tank id out of the range 0 to 3. So the organizers must have changed the test harness after the final submission date, in which case it nullifies its purpose as a test harness. I could choose to be bitter about this.

My second choice is to suck it up and learn from the mistakes that I made. And I can only do that if I don't take the easy way out by blaming someone else for what went wrong (tempting though that is).

I used a variety of defensive coding practices, including my fail-safe algorithm. But I failed to code defensively against the possibility of the tank id's being outside the range of 0 to 3. I have a vague memory of feeling very uncomfortable at making this assumption. But I made the poor judgement call of ignoring my intuition and going with a cheap solution rather than the right solution (or even just a cheap solution with more defensive coding). That mistake is my mistake, and it's something I can learn from.


Keeping the goal in mind

The big picture with entering competitions like this, is that you are not doing it for the prize money or the fame (though those are useful motivators to help give you a focus for your efforts). Doing so would be a form of moonlighting and is arguably unethical.

To some extent you are doing it for the fun and the camaraderie - the opportunity to interact with smart developers who enjoy challenging themselves with very tricky problems. But I get similar enjoyment from playing German-style board games with my colleagues and friends - and with far less investment of time.

However the most important reason is for the learning experience. You are exposing yourself to a challenging situation which will stretch you to your limits, and in which you are bound to make some mistakes (as well as learn new coding techniques). The mistakes you make and the lessons you learn are part of your growth as a programmer.

With this perspective I would rather learn from my mistakes than look for someone to blame.

The alternative is to become bitter at the injustice of the situation. But life is full of injustice, and in many cases (such as this one) it is not caused by malevolence, but simply by human fallibility. As software developers we know all too well how seemingly innocuous changes can have unexpectedly large side-effects.

I'm not advocating that we should lower the standards we set for ourselves and others. But I think we should balance that against having the maturity to forgive ourselves and others when we make unfortunate mistakes despite our best intentions.


The most valuable lesson I learnt

The most valuable lesson learnt was not about coding more defensively. Or about making testability a primary consideration. Or to avoid premature optimization. Or even to listen to my gut feeling when I'm feeling uncomfortable about code that I'm writing (valuable though that is).

Those are all things I already knew. As the saying goes, experience is that thing that allows you to recognise a mistake when you make it again!

The most valuable lesson was a new insight: beware of the second system effect!

Last year I placed fourth in the challenge with a fairly standard NegaMax search tree approach. I was conservative in my approach, did the basics well, and got a great result! But I had some innovative ideas which I never got as far as implementing...

This year I wanted to do better than last year. And I wanted to push the envelope more. And as a result I fell foul of the second system effect, and did worse than last year.

And this is not the only recent instance of this happening...

In 2011 I did really well in the UDT Super 15 Rugby Fantasy League with a simple statistical model (built in Excel) and a linear programming model for selecting my Fantasy League team each round. And I placed in the 99.4th percentile (183rd out of around 30 000 entrants)!

In 2012 I wanted to do even better, so I used the R programming language to build a much more complex statistical model. I put a lot more effort into it. Yet I only placed in the 90th percentile. The second systems effect again!

In both cases I learnt far more from my second system than from the more conservative (but more successful) first system. So it's not all bad, since learning and self-development is the primary goal. But in future I'd like to find a better balance between getting a good result and "expressing my creativity".


Wrap-up

As one of the eight finalists in the 2012 competition, I ended up being interviewed after the play-offs last year. That interview can be found on youtube.

Although I didn't make it to the final eight this year, I still found myself being roped into an interview. I'll update this page with the link once that interview has been uploaded to youtube.

For anyone who's interested, I've also uploaded the source code for my bot entry on GitHub.

There's more detail on the approach that I and the other contestants took at this page on the google groups forum.


What's next?

At some point I'd like to post a blog entry on my shortest path algorithm, as I came up with a neat trick to side-step the various complexities of doing a Dijkstra algorithm with binary heaps, pairing heaps, r-divisions on planar graphs, and so forth.

But first I'd like to wrap up my series of posts on an interesting problem in recreational Mathematics known as the Josephus problem.


Friday, September 13, 2013

The past two months...

A break from blogging

Over the past 2 months I've taken a break from blogging.

During that time I've spent a week in the Kruger park, worked crazy hours on a software architecture investigation for a client, and worked equally crazy hours in my spare time on the 2013 Entelect Artificial Intelligence competition.

This blog post is a recap of those 3 activities.


The Kruger Park

I took my family camping at Punda Maria campsite in the Northern section of the Kruger Park from 14 to 19 July.

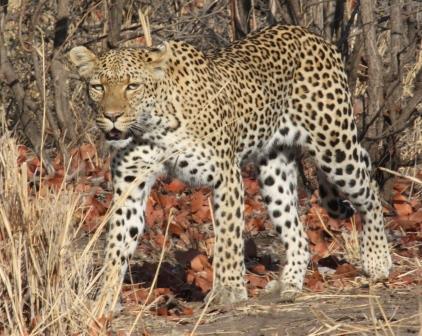
Back in 2008 we had one or our best Kruger trips ever in that part of the park, seeing no less than 4 leopard, including an excellent sighting where the leopard was metres from our car. So we had extolled the virtues of Northern Kruger to our friends John and Sarah, who were accompanying us with their 3 children.

A leopard sighting from our trip to Northern Kruger in October 2008
This time was very quiet, however, as the floods earlier in the year had allowed the animals to disperse much further than they normally would in the dry month of July. We narrowly missed seeing a leopard near the campsite and we only heard the lions at night.

In my opinion, Northern Kruger is the most beautiful part of the Kruger park, particularly the area near the Pafuri picnic site and along the Nyala drive. So although we were disappointed at not seeing any of the big cats, we still enjoyed our visit immensely.

Northern Kruger has a reputation for being a birders' paradise, and we certainly saw our fair share of beautiful birds. I even managed to capture a Lilac-Breasted Roller in flight, something I had tried many times before without success.

A lilac-breasted roller in flight

A korhaan sighting on the way back from Pafuri

A hornbill that scavenges left-overs at the Babalala picnic area
 

An architectural investigation

On returning from Kruger, I jumped straight into a 4 week architectural investigation for a client. The client was concerned about their dependence on a 3rd party integration hub whose host was experiencing financial uncertainty. My role was to assist the client in understanding their IT ecosystem, assess their and their business partners' dependencies on the 3rd party vendor, and provide a roadmap (with estimated costs) for mitigating the risk.

This is very different from the work that I do on a day to day basis. Most of the time I am one of the software designers/architects on a team of 25 to 30 developers, testers, business analysts, architects and project managers. I spend my day doing UML diagrams for new features, assisting developers when requested, estimating task sizes, performing code reviews, troubleshooting performance issues, and so forth. In other words, I am very much a cog in a bigger machine.

With the architectural investigation I was on my own. I had complete autonomy to carry out the investigation as I saw fit. I love doing investigative work. I love work that has strategic impact. I love feeling my way towards a solution. So I revelled in this independence.

Although exciting, it was very intense work too. On Friday 16 August I gave a presentation of my findings to the technical stakeholders. I worked right through the night on both the Tuesday and Thursday night beforehand, clocking over 25 hours of work on Tuesday and Wednesday, and over 27 hours on Thursday and Friday.

I've done all-nighters before in my career. But never two in one week. It's definitely not something I would recommend...

I was very happy with the outcome of the work though, and the presentation seemed to go very well, despite getting off to a slow start due to my lack of sleep and the adrenalin of putting the finishing touches to the presentation only minutes before the meeting started!

The final presentation to the executive committee took place the following Tuesday. The previous presentation had included a lot more technical detail, and the focus had been on presenting a wide variety of options. The final presentation was much more condensed, and focused on 2 primary recommendations. The presentation went extremely well, and the feedback was very positive - both from the customer's CFO and from a number of my superiors at Dariel.

A few days later I was asked whether I would like to do similar investigations in future. I replied that this was similar to asking someone who has just completed the Comrades Ultra-marathon whether they would like to do it again next year!


The 2013 Entelect AI Challenge

Last year I participated in the inaugural Entelect R 100,000 Artificial Intelligence Challenge. I was delighted to place 4th out of 101 contestants.

I was really hoping to better that this year. However the 2013 challenge took place over the same period as the trip to Kruger and the architectural investigation. Additionally, last year's contestants had from mid-July until 24 September to submit their entries. This year the closing date was 2nd September. So there was simply less time to recover from the long hours on the architectural investigation.

This year's competition was to program two tanks to take on two other tanks on one of 8 boards, up to 81x81 squares in size, in a simultaneous movement tank battle based loosely on the 1980's arcade game Battle City, and using SOAP web services to communicate to the server. This was a massive jump in complexity from last year's competition, which was a Tron-like turn-based game with one unit per player, played on a 30x30 sphere with communication via reading and writing a text file.

If I was a wiser man, I would have thrown in the towel before even starting. Fortunately I'm not!


I started my career as an Operations Research consultant at the CSIR and I still retain a strong passion for decision optimization and decision automation. My outlet for that passion is entering competitions like the Entelect AI Challenge.

It's also a great way to keep my coding skills current, as my role as a software designer means that I don't get to write as much production code as I would like.

So, against my better judgement, and despite all obstacles, I have participated in the Entelect programming challenge again this year! It's been very tiring and the stress levels have been immense. I have barely lurched over the finish line, assisted in no small measure by the final entry date being extended by a week from 2nd September to Monday 9th September.

But at least I have managed to complete an entry. And one that I'm reasonably proud of, even though I don't think it will be good enough to get me to the final 8 like last year.

The camaraderie last year was amazing, and the way the contestants have assisted and encouraged each other in this year's competition has been no less amazing. You would never guess we were competing with each other for a prize of R 100,000 (roughly $10,000). That's a lot of money and the prize for second place is tiny by comparison. But you'd never guess it by the way contestants have generously shared advice with each other, and encouraged each other to keep going when it gets tough. And believe me, this has been a very tough challenge this year (as shown by the far smaller number of people who got as far as submitting an entry).

The play-offs for the competition take place tomorrow evening at the Fire and Ice Protea Hotel in Melrose Arch, Johannesburg. I will be there to share in that spirit of camaraderie again.

Although my expectations for my bot are low, my hopes are high. I'm hoping that my bot gives it horns...


... and that some remaining bug doesn't sabotage my efforts and leave me meekly hiding in the shadows!


What comes next?

I'm still busy with a couple of blog postings for the problem of calculating the last person left in a circle if every second person is asked to leave. I hope to post those shortly and close off the series.

I worked out a few very nice algorithms for the Battle City AI challenge. So I'd like to write a series of articles on those as well. I'd also like to analyse some of the mistakes I made in the competition, and what I would do differently if I could start over.

And once my bot is knocked out the competition I'm planning on posting the code for my entry to GitHub.

I suspect this will be of interest to the other contestants in the competition (we have already been doing post-mortems of our strategies on the unofficial google groups forum for the competition). But it may also have a few nice ideas that will be useful to people competing in other AI competitions in future.

So please keep a lookout for those!